385e75e9a9
* perf(persistence): skip annotation join in CountAll when unused

The Native API list endpoints (/api/song, /api/album, /api/artist) issue a
pagination count on every request via rest.GetAll. CountAll unconditionally
added a LEFT JOIN on the annotation table to a count(distinct id) query. The
join's columns are stripped by count(), but the distinct-over-join forced
SQLite to stream and dedup every row, making the count dominate the request
time on large libraries (e.g. ~190ms cold for 95k songs, seconds for
non-admin users behind the library subquery).

Gate the annotation join: only add it when a filter actually references an
annotation column. The need is detected by rendering the query to SQL and
matching annotation column names as whole words, which covers both named
filters (starred, has_rating) and raw squirrel filters. The column set is
derived from model.Annotations so it tracks schema changes; average_rating is
excluded because it lives on the base table, and word-boundary matching keeps
it from matching the annotation column rating.

Counts are unchanged; only the query plan changes. Unfiltered song counts drop
from ~37ms to ~4ms (warm) on a 95k-song library.

* test(persistence): make annotation-join detection case-insensitive

Address review feedback: SQLite column names are case-insensitive, so a raw
filter using e.g. "RATING" would previously evade the case-sensitive column
regex and wrongly drop the annotation join. Add the (?i) flag (average_rating
stays excluded — the underscore still prevents a word boundary before rating)
and cover it with mixed-case tests. Also make the starred-count assertion an
exact value instead of a range.

Navidrome Music Server 



Navidrome is an open source web-based music collection server and streamer. It gives you freedom to listen to your music collection from any browser or mobile device. It's like your personal Spotify!
Note: The master branch may be in an unstable or even broken state during development.
Please use releases instead of
the master branch in order to get a stable set of binaries.
Check out our Live Demo!
Any feedback is welcome! If you need/want a new feature, find a bug or think of any way to improve Navidrome, please file a GitHub issue or join the discussion in our Subreddit. If you want to contribute to the project in any other way (ui/backend dev, translations, themes), please join the chat in our Discord server.
Installation
See instructions on the project's website
Cloud Hosting
PikaPods has partnered with us to offer you an officially supported, cloud-hosted solution. A share of the revenue helps fund the development of Navidrome at no additional cost for you.

Features
- Handles very large music collections
- Streams virtually any audio format available
- Reads and uses all your beautifully curated metadata
- Great support for compilations (Various Artists albums) and box sets (multi-disc albums)
- Multi-user, each user has their own play counts, playlists, favourites, etc...
- Very low resource usage
- Multi-platform, runs on macOS, Linux and Windows. Docker images are also provided
- Ready to use binaries for all major platforms, including Raspberry Pi
- Automatically monitors your library for changes, importing new files and reloading new metadata
- Supports lyrics from sidecar .ttml, .yaml/.yml Lyricsfile, .elrc, .lrc, .srt, .txt files and embedded TTML, Enhanced LRC, LRC, SRT, and plain-text tags (via
lyricspriority) - Themeable, modern and responsive Web interface based on Material UI
- Compatible with all Subsonic/Madsonic/Airsonic clients
- Transcoding on the fly. Can be set per user/player. Opus encoding is supported
- Translated to various languages
Translations
Navidrome uses POEditor for translations, and we are always looking for more contributors
Documentation
All documentation can be found in the project's website: https://www.navidrome.org/docs. Here are some useful direct links:
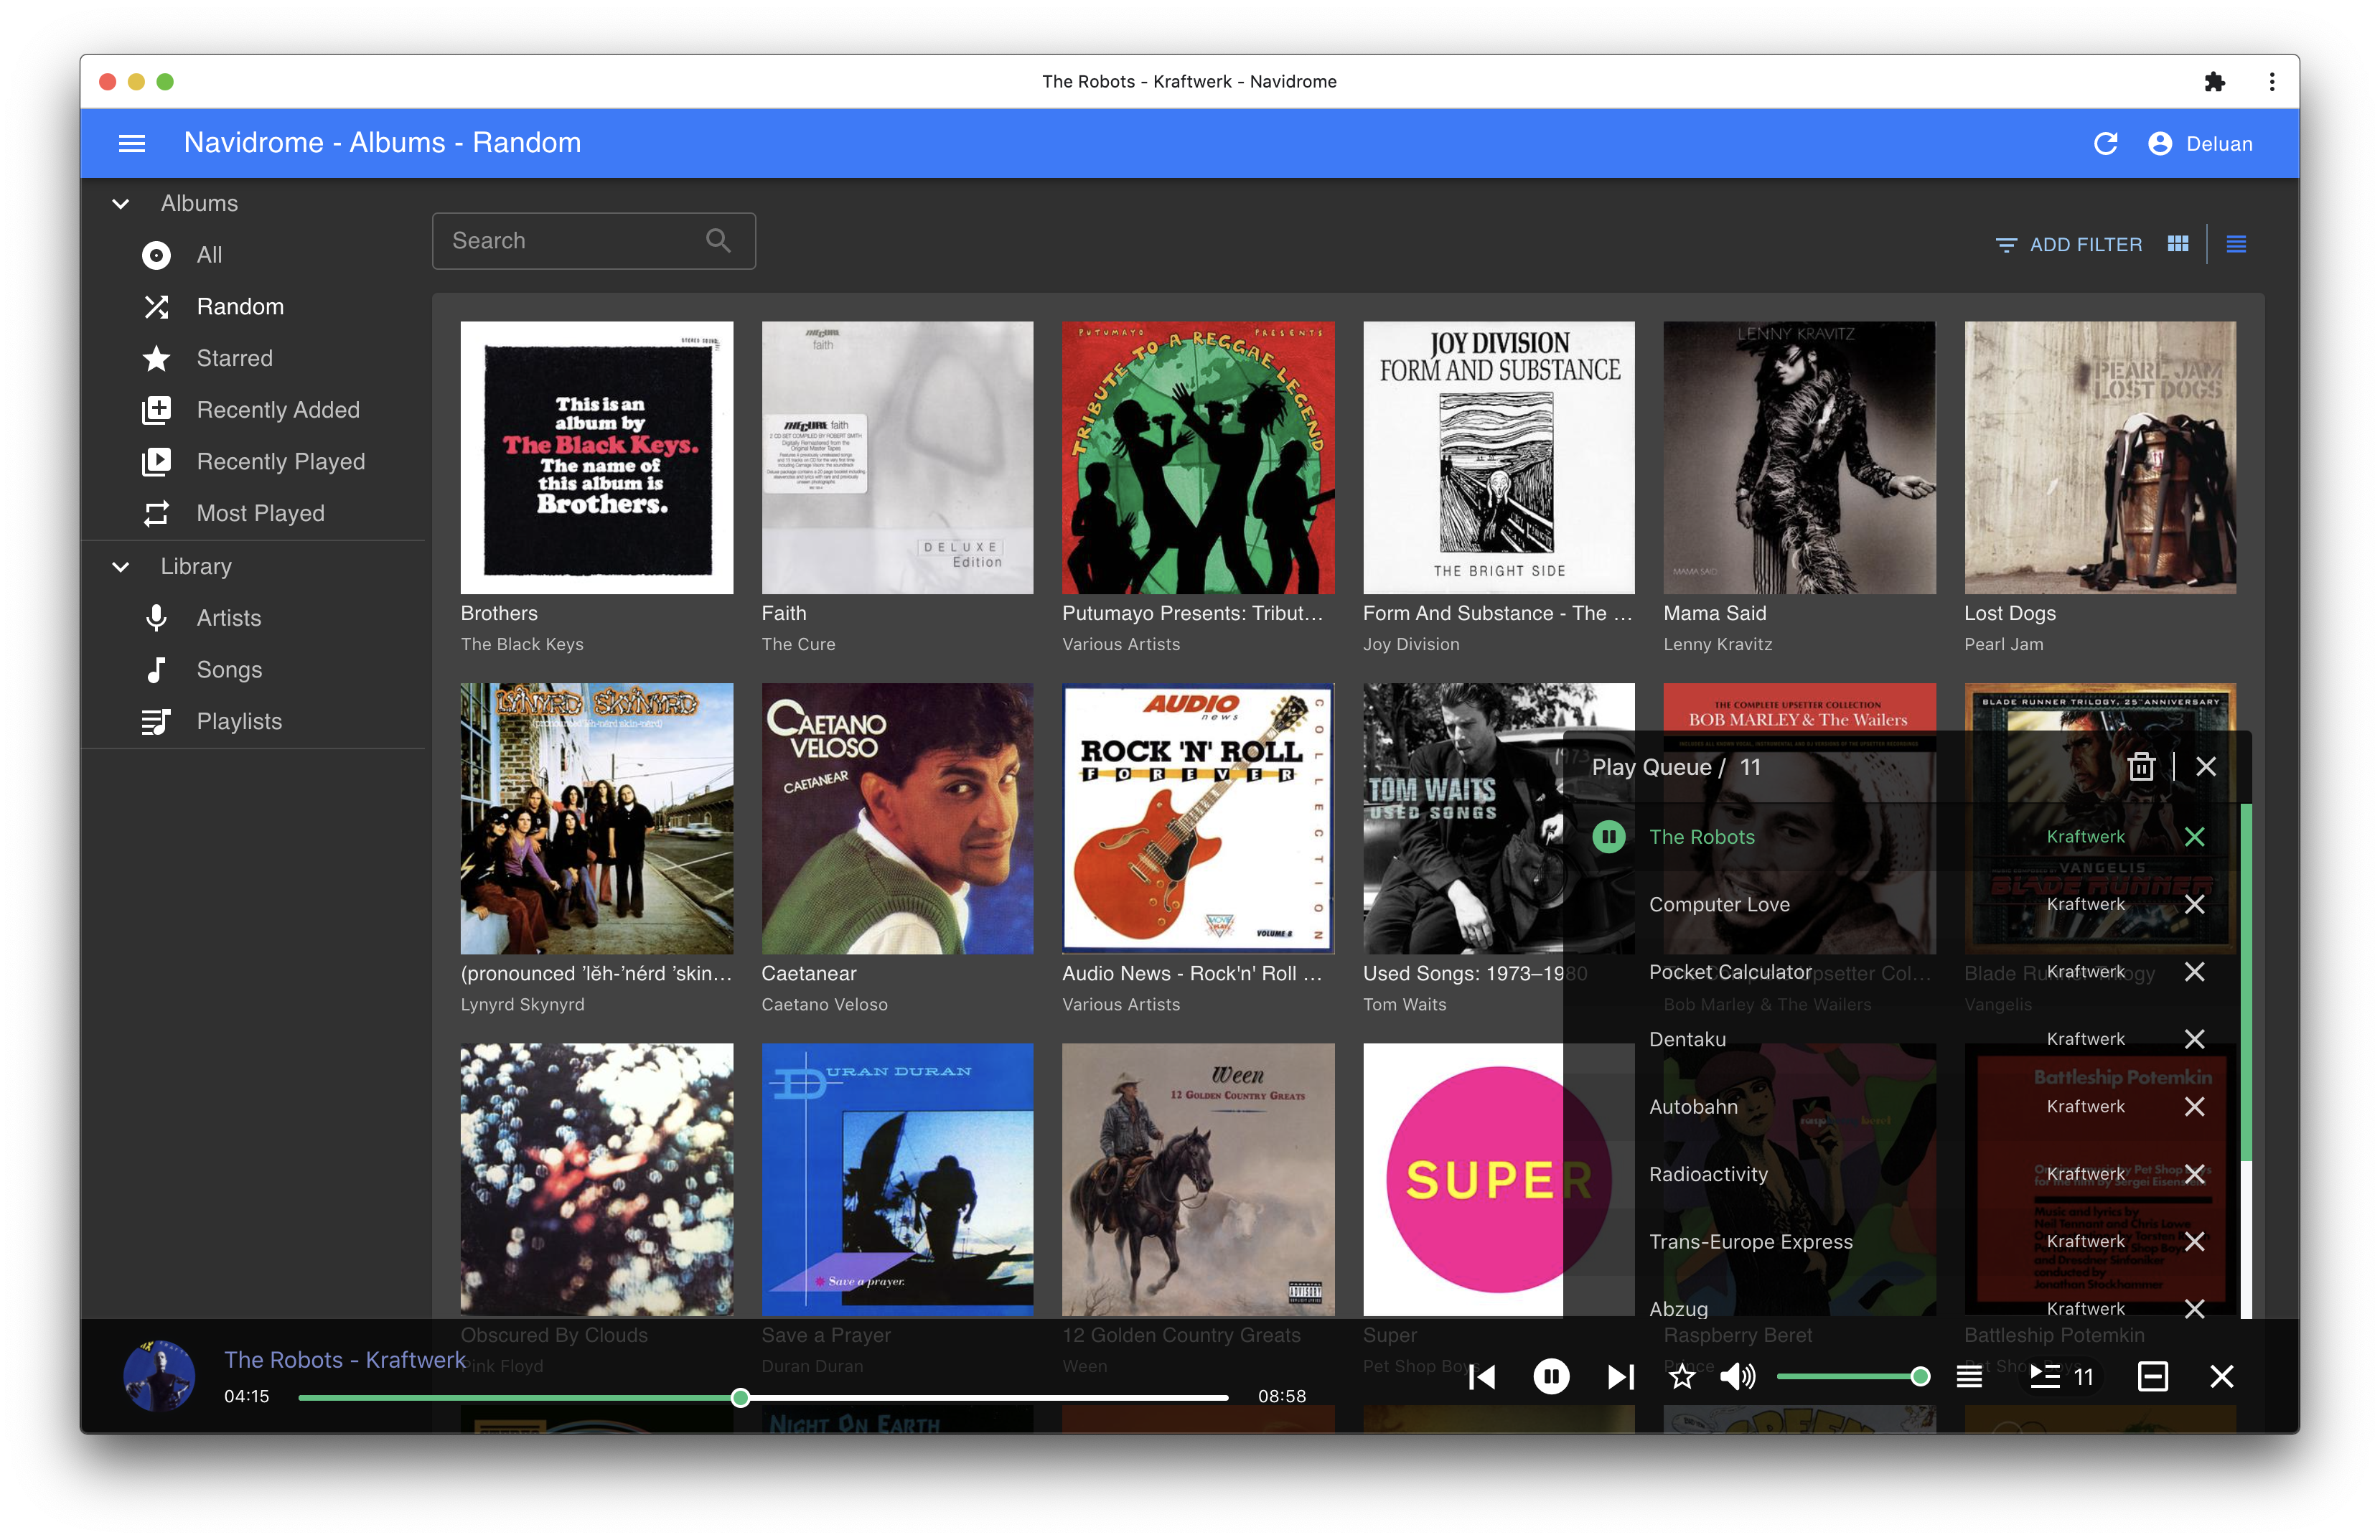
Screenshots